
Ismail
by
Generate, edit, render, and analyze music programmatically using text‑based commands, enabling AI agents to compose and perform tracks live.
Ismail Overview
What is Ismail about?
Ismail is a digital audio workstation designed to be driven entirely by text. An AI agent writes a song as notes, instrument patches, effect chains and automation; the system renders the audio, reads back analytical data as text, and can play the track live while the agent continues to edit.
How to use Ismail?
- MCP server: start the server with
python -m ismail.mcp_server. The server exposes ~90 tools that MCP‑compatible clients (Claude Code, Cursor, etc.) can call. - CLI: run operations directly, e.g.
python -m ismail -p songs/demo project_new bpm=124 length_bars=8orpython -m ismail -p songs/demo render stems=true out=v1 mp3=also. - Python API: import
from ismail import apiand invoke the same operations programmatically. - Skill integration: a ready‑made Claude/Cursor skill (
skills/ismail) provides prompts and workflow templates for agents.
Key Features
- Iterative editing: change any single note, patch, bar or fader and re‑render without affecting the rest of the project.
- Code‑centric workflow: projects are plain folders with
project.jsonand a build script, fully version‑controlled (git history, diffs, branches). - Fully extensible sound sources:
- Sprite synth engine with extensive oscillator and filter options.
- Mimic profiles measured from real recordings (violin, cello, etc.).
- Sampler and custom Python voice modules.
- Comprehensive analysis tools: tempo/grid detection, structure, chords, drum patterns, spectral/timbre analysis, CLAP perceptual similarity, and more – all return structured text.
- Live engine: real‑time playback with decks, transitions, and live‑looping; the same code used for rendering runs in the live mixer.
- Optional extras: perceptual metric (CLAP), source‑separation with Demucs, live playback via
sounddevice, and a music‑video pipeline using Blender. - Cross‑platform: works on Windows, macOS and Linux; OS‑specific TTS for vocal samples.
Use Cases
- AI‑driven composition: let large language models (Claude, Cursor, etc.) compose music by issuing text commands.
- Automated remixing / DJ sets: queue tracks, blend decks, and apply live effects while the AI edits on‑the‑fly.
- Reference‑based production: import a reference track, analyze its structure and sound, then automatically fit synth patches and balances to match.
- Research & education: study algorithmic composition, audio analysis pipelines, or train models on text‑to‑audio workflows.
- Custom sound design: create and share voice modules or mimic profiles, then reuse them across projects.
FAQ
Q: Do I need a GPU? A: Only the optional perceptual CLAP metric and Demucs separation benefit from a GPU; the core engine runs on CPU.
Q: Can I use Ismail with other AI agents? A: Yes. Any client that speaks the MCP protocol can call the server; the provided skill is just a convenience for Claude and Cursor.
Q: How are audio files stored?
A: Rendered WAV files are saved under renders/; MP3s are optional. All analysis tools read from these files.
Q: Is there a pre‑built library of instruments?
A: The ismail/voices/ folder contains built‑in synth patches, measured instrument profiles, and code‑based voices. Users can add their own modules via the $ISMAIL_VOICES path.
Q: What licensing applies? A: Ismail is released under the MIT license.
Ismail's README
ismail
A DAW for AI agents. It can't hear, so it reads. And it plays live.
Your agent writes the song as notes, sounds and code, reads back what it made, and then performs it: DJ decks, transitions, requests taken while the music plays.

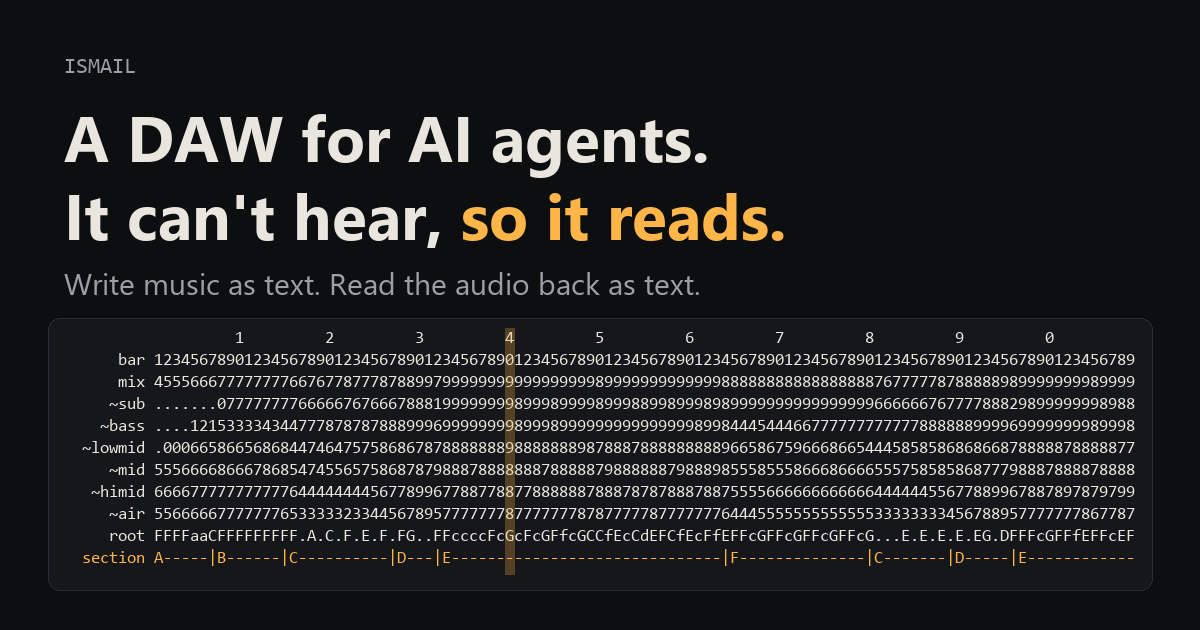
Listen to songs an agent made with it, each shown with the text the agent read while making it. The playhead runs across that text as the song plays.
| song | what it is |
|---|---|
| Live set: Clash, Poppycock, Mycelium | recorded live: the agent plays three of its songs in full on decks at 150 BPM (orchestral into dubstep into psytrance), each blended into the next, every song re-rendered from its notes |
| Tidewater | strings measured from recordings (mimic), piano, taiko and gong; 22 dB from a pianissimo solo cello to the fortissimo tutti |
| Mycelium Protocol | psytrance at 145 BPM, sounds fitted to a reference record's drums and bass |
| Poppycock | dubstep, one bass voice whose note velocity picks each hit's articulation |
| Fantaisie-Impromptu | Chopin on a piano synthesized from measured notes, no samples |
| AstraSMB | drum and bass at 174 BPM |
| Clash | hybrid orchestral fight cue, every instrument synthesized |
| Two Kinds of Tears | solo piano, a minor theme that returns in major |
| Bass of Storms | fan remix of Song of Storms as dubstep |

Luigi Manson, made with ismail (fan remix of the Luigi's Mansion theme).
Not a music generator
ismail is not a model that turns a prompt into audio, like Suno. It is a set of tools your own agent uses to write the song as notes, sounds and code, render it, read back what came out, and edit it. That changes what you get:
- Iterative, precise edits. Change one note, one patch, one bar or one fader and re-render; nothing else moves.
- Songs are code. A project file and a build script: git history, diffs, branches and code review work on a track.
- Any sound. Synths, drum synths, samplers, voices written in Python and speech; any sound can become an instrument.
- Local and open. MIT licensed, runs on your machine, no content filter and no music subscription (you bring the agent).
- It improves with your model. The music is the agent's own work, so a stronger model with the same prompt should write a better song.
- It plays live. The same songs, instruments and effects run in real time: the agent loads finished songs on decks and mixes them, jams with you, and changes the music between its turns while it keeps playing. A text-to-song service hands you a finished file; streaming models such as Lyria RealTime steer a style with prompts, but cannot play the exact song you wrote or change one bar of it.
Suno is still better at realistic sung vocals, a polished song from one sentence in under a minute, and genre sound learned from recorded music. And why not Ableton or FL Studio? They were built for a person with ears and a mouse; an agent can press their buttons through bridges but still can't hear what it did. ismail puts everything an agent needs to write and to perceive into compact text, and if something is missing, your agent can add it. More on the showcase page.
What it is
A DAW built to be operated by an AI agent. Everything goes in as text (notes, instrument patches, effect chains, automation) and everything comes back as text: levels, spectra, drum patterns, piano rolls, chords, vowels, song structure, and structured comparisons against a reference track. The agent never needs ears or images to work (a spectrogram PNG is there if you want one).
One set of operations, three ways in:
- MCP server for Claude Code, Cursor or any MCP client:
python -m ismail.mcp_server(stdio, 90 tools) - CLI:
python -m ismail -p <project> <op> [args] - Python:
from ismail import api
Install
Python 3.10 or newer.
git clone https://github.com/newsbubbles/ismail
cd ismail
pip install -e .                      # engine, analysis, CLI, MCP server
pip install -e ".[perceptual]"        # optional: CLAP perceptual metric (torch + transformers, model about 600 MB)
pip install -e ".[separate]"          # optional: demucs stem separation for reference tracks
pip install -e ".[live]"              # optional: play live to your speakers (sounddevice)
If demucs fights your torch install, use pip install --no-deps demucs and then pip install dora-search einops julius lameenc openunmix.
MP3 previews need ffmpeg on your PATH (or set ISMAIL_FFMPEG to the binary).
Runs on Windows, macOS and Linux; CI tests all three on every push. The one OS-specific op is sound_speak (text to speech for vocal samples), which uses the engine the OS already has:
| OS | Engine | Voices |
|---|---|---|
| Windows | SAPI via PowerShell | David, Zira, any installed |
| macOS | say |
Samantha, Alex, anything in say -v ? |
| Linux | espeak-ng or espeak |
en-us, en+f3 ... (sudo apt install espeak-ng) |
Use it with Claude Code
-
Tools. Open Claude Code in this folder and the bundled
.mcp.jsonregisters the server; the tools show up asmcp__ismail__*. To use ismail from any folder instead:claude mcp add -s user ismail -- python -m ismail.mcp_server -
Skill (recommended).
skills/ismailteaches the agent how to compose with ismail: plan a Session Sheet before writing notes, write a Listening Report after every render, and judge reference matches with the comparison tools instead of by feel. Link it into your skills folder:# macOS / Linux ln -s "$(pwd)/skills/ismail" ~/.claude/skills/ismail# Windows New-Item -ItemType Junction -Path "$env:USERPROFILE\.claude\skills\ismail" -Target "$PWD\skills\ismail" -
Ask for music. For example: "make a 16 bar deep house loop in F minor in songs/demo and render an mp3". The agent calls
guideonce for the conventions (it is a tool and a CLI op), then works through the tools.
Use it with Cursor
-
Tools. Opening this folder in Cursor picks up
.cursor/mcp.json. To use ismail in other projects, add the same entry to~/.cursor/mcp.json:{"mcpServers": {"ismail": {"command": "python", "args": ["-m", "ismail.mcp_server"]}}} -
Skill.
.cursor/rules/ismail.mdcis an agent-requested rule that points Cursor's agent atskills/ismail/SKILL.md. Copy that rule (and theskills/ismailfolder) into another project to use it there.
Any other MCP client works the same way: run python -m ismail.mcp_server over stdio.
Quick start (CLI)
Every tool is also a CLI op. Arguments are key=value pairs (values parsed as JSON when they can be) or one JSON object.
python -m ismail guide                                # read first: workflow and conventions
python -m ismail ops                                  # list operations
python -m ismail help notes_write                     # one op's arguments and docs
python -m ismail -p songs/demo project_new bpm=124 length_bars=8
python -m ismail -p songs/demo track_add name=bass instrument='"preset:acid_bass"'
python -m ismail -p songs/demo notes_write '{"track": "bass", "bar": 1, "notes": "0 E2 0.5 110; 0.5 E3 0.25", "repeat": 8}'
python -m ismail -p songs/demo render stems=true out=v1 mp3=also
python -m ismail -p songs/demo analyze_melody source=track:bass bars=[1,2]
render writes renders/latest.wav (every analysis tool reads it), plus renders/<out>.wav when you name the render. mp3='also' adds renders/<out>.mp3 for listening; mp3='only' writes the named render as mp3 only.
Keep your projects under songs/ (git-ignored) or anywhere else; a project is just a folder.
Concepts
- Project: a folder with
project.json(tempo, grid offset, tracks, buses, master, sound bank, reference) plussounds/,renders/,cache/,history/(undo snapshots) andcomparisons/. - Time: bars are 1-indexed; note times are beats relative to the bar you write at.
offset_secis the time of bar 1, so a project can sit exactly on a reference recording's grid. - Notes:
'<beat> <pitch> <dur> [vel]', one per line or;-separated. Drum and step patterns:pattern_writewith strings likeX...x...X...x...(X 127, x 100, o 70, - 45,_ties). - Instruments: two synth engines. sprite (
"type": "synth"or"sprite": saw, square, pulse, triangle, sine, additive, wavetable and noise oscillators, unison, FM, drive, SVF and ladder filters, envelopes, LFOs, mono glide) is right for synth sounds. mimic ("type": "mimic") plays instruments measured from recordings (see below). Plussampler, drum synths (kick,snare,hat,clap,tom,noise_hit),kit(pitch to instrument map) andcode(a Python voice function for anything else).presets_listhas starting points. - Effects: eq, filter, distortion, bitcrush, compressor (with sidechain), duck, gate, delay, reverb, chorus, flanger, phaser, tremolo/autopan, width, limiter, vocoder, formant, and a guitar rig: fuzz, univibe, amp (tone stack, power stage with sag), cab, rotary speaker, tape, wah. Tracks, buses and the master fader can be automated.
- Voices: engineered instruments kept as Python modules, so a project stores a name instead of code (see below).
- Sound bank: sounds made from any instrument and effect chain (
sound_make), speech (sound_speak), imported files, and averaged events cut from a recording (sound_extract). Bank sounds work as sampler sources, wavetables, vocoder modulators and audio clips. - Undo and batch: every edit snapshots the project (
undo);batchapplies a list of ops atomically.
Voices: instruments as code
Some instruments are easier to write than to patch: a measured grand piano, a dubstep bass whose note velocity picks the articulation, a set of sound effects. These live as voice modules, Python files that define voice(freq, t, vel, gate, sr) and return a mono (n,) or stereo (2, n) array. freq is in Hz, t is an array of seconds from the note start that covers the held time plus the instrument's tail, vel is 0 to 1, gate is how long the note is held in seconds, and sr is the sample rate.
The library is grouped in family folders under ismail/voices/; names stay flat, so a track says "voice": "grand_piano" whatever folder it lives in, and voices_list shows the family.
| family | voice | what it is |
|---|---|---|
| keys | grand_piano |
grand piano calibrated from measured notes (partials, decay times, inharmonicity, stereo image, hammer knock, dampers); fn: voice_sym is an undamped sympathetic string |
| keys | additive_piano |
a lighter additive piano with no data file |
| strings | violin, cello, contrabass |
mimic profiles measured from real recordings (use {"type": "mimic", "profile": "violin"}); open strings, measured room and vibrato included; params.players makes a section |
| bass | growl |
dubstep bass engine: velocity 1x yoi, 2x wub, 3x screech, 4x metal, 5x dive, 6x zap, 7x grind, 8x chop, 9x talk, 11x robot, 12x howl; the LFO rates follow the song tempo |
| fx | sfx |
one-shots by velocity: gunshot, reload, shell casing, bone crunch, punch, rip, gong |
| guitar | electric |
performer: electric guitar or bass as waveguide strings (pick, pickup comb, pickup resonance) playing a whole part, with legato, slides, bends, whammy, vibrato and mutes as lanes. Presets strat70_lead, strat70_rhythm, strat70_rotary, pbass70; it is the DI signal, so voice_help lists the rig each preset was fitted with |
| drums | kit70 |
performer: a 1970 acoustic kit as modal resonator banks that keep ringing across the part (a ride builds wash); preset kit70 and its fitted EQ |
Use one with instrument={"type": "code", "voice": "grand_piano", "tail": 4.0} or "preset:grand_piano". voices_list shows what is available and voice_help(name) explains a voice's velocity mapping, functions and parameters.
Voices are looked up in this order:
<project>/voices/<name>.py: the song's own. Same name as a built-in overrides it; a song voice can also extend one (from ismail.voices.growl import *, then add words or articulations).- Each folder in
$ISMAIL_VOICES(a path list): your personal library, outside any repo. ismail/voices/: the built-ins.
Each of these may have family subfolders (strings/, keys/, percussion/ ...), searched too; mimic profiles (<name>.mimic.json) are found the same way.
A voice function may take extra keyword arguments: bpm is passed automatically, and the track's "params" dict is passed as keywords ({"type": "code", "voice": "mine", "params": {"brightness": 0.3}}). A module-level INFO dict documents it for voice_help; every key is optional: summary (one line for voices_list), range, velocity (what velocity does), functions (name to description), params (name to description), lanes (a performer's expression lanes), rigs (fx chains it was fitted with, each with its preset) and tail (recommended tail).
A performer voice defines perform(notes, total_n, sr, bpm, lanes, **params) instead of voice(): it gets the whole part at once, so strings ring on under the next note, legato notes slide or hammer on, and a lane bends everything that sounds. Lanes come from automation inst.lane.<name> in the studio and from clip expr live (a deck converts one to the other). Data files sit next to the module (grand_piano.json) and are found through __file__. Editing a voice file invalidates the render cache for the tracks that use it.
To add a voice to the library, move it from a song's voices/ folder into the right family folder under ismail/voices/ (a new family needs an empty __init__.py and a line in pyproject.toml), give it an INFO dict, and add a line to the test that renders every built-in (tests/test_library_performers.py for performers).
mimic: instruments measured from recordings
A synth patch pretending to be a violin sounds like a 1990s game console playing a violin. mimic starts from recordings instead. Give it a few isolated notes of an instrument and it measures, per note:
- every harmonic's level and envelope (attack, sustain or two-stage decay, release), inharmonicity, and the beating between unison strings;
- a body curve fixed in frequency (the resonances that color each note differently), separated from each note's source slope;
- the noise between the harmonics and a short map of the attack (bow scrape, hammer knock), both calibrated by rebuilding the note and matching the recording; attack timing from short windows, so a player easing into the string eases in;
- vibrato cycle by cycle: rate, depth, how much each wanders over about a second, and how it builds up; the slow swells of a bowed or blown note;
- the room the recordings were made in, from how every harmonic dies away after the bow stops.
Then it plays any pitch: notes between measured ones blend their two neighbours, every harmonic reads the body at its current frequency (so vibrato moves the color the way a real instrument does), unison strings start in phase and beat, and each note varies a little. Optional: open strings ringing in sympathy, the body ringing, noise skirts around the harmonics.
python -m ismail -p song mimic_measure name=violin folder=samples/violin 'defaults={"strings": ["G3", "D4", "A4", "E5"]}'
python -m ismail -p song track_add name=fiddle 'instrument={"type": "mimic", "profile": "violin", "tail": 1.0}'
folder holds one note per file named by pitch (A4.wav, Fs3.mp3); notes=[[source, pitch], ...] takes sound-bank names, paths or windows of a longer file. The profile is written to <project>/voices/violin.mimic.json and found like a voice (voices_list shows it). mimic_measure rebuilds every measured note from the others and reports how close each lands, which is the honest estimate for pitches you did not record, and it uses that test to choose how sharp the body curve can be for your data. instrument_help(type='mimic') lists the playing parameters.
Tested leave-one-out on violin, cello and double bass recordings, a mimic note rebuilt without ever hearing that note lands as close to the real one as a real neighbouring note repitched, or closer (violin 11.2 vs 14.6, cello 12.5 vs 13.0, double bass 10.9 vs 12.8 on sound_compare's distance), and about three times closer than a hand-set sprite patch. The defaults were then tuned by ear over four rounds of blind A/B "eye exams" against the recordings (real note vs versions that each change one named thing); the current default won every note of the last round. Struck and plucked instruments (piano) are harder: with 12 notes across 7 octaves a piano's note-to-note colour can't be predicted and mimic stays behind a sampler there (16.3 vs 11.6); the grand_piano voice remains the better piano. A few notes at one dynamic teach one dynamic: record soft and loud notes if velocity matters, and more notes than you think for instruments whose colour changes from note to note.
Hearing: audio as text
| Question | Tool |
|---|---|
| Tempo, where bar 1 is, tuning, swing | analyze_grid (bar 1 voted by kick, harmony, section changes and the snare on 2 and 4), align, analyze_swing |
| Song form, what plays where | analyze_structure (arrangement map, sections, loop length, root per bar) |
| Levels, bands and chords per bar | analyze_bars, analyze_chords, analyze_key |
| Drum pattern | analyze_drums (step strings you can paste into pattern_write) |
| What is in a drum kit | analyze_kit (splits a drum stem into its pieces, with each one's pattern and audio) |
| Loudness per section, dynamic range | analyze_sections (warns when a build is as loud as its climax) |
| Notes | analyze_pitches (per beat), analyze_roll (piano roll), analyze_melody, analyze_notes |
| Rhythm of level (pumping, gating) | analyze_envelope |
| What a sound is | analyze_timbre, analyze_spectrum, sound_compare |
| Vowels of a voice | analyze_formants |
| A picture, if you really need one | spectrogram (PNG) |
Sources are render, track:<name> (after render(stems=True)), ref, ref:<stem>, sound:<name> or a file path.
Recreating a reference track
Bring your own reference audio (project_new(..., reference=<file>)); none is included here.
analyze_grid(source='ref'), thenaligna rendered drum track againstref:drumsand correctoffset_sec. If it reports the record 15 cents or more off A440 (a sped-up sample), runref_retune()first: otherwise every note reads as a pair of semitones.separate(source='ref')(demucs) and readanalyze_structure(source='ref'). Measure the drums before writing them:analyze_swingandanalyze_kit(source='ref:drums').- Transcribe with
notes_from_audio_loop. It keeps only notes that recur across repetitions of the loop, because raw transcription copies echoes, leakage and distortion partials as hard notes. If the song alternates versions of its loop, transcribe each from its own repetitions and passbase_barsso the shared notes stay identical. - Design sounds:
sound_extracta repeated hit or stab, theninstrument_fit(evolution strategy over instrument and effect parameters, scored on spectrum, envelope, width and pitch clarity).track_fittunes a part in context against the reference stem. stem_map_set,render(stems=True),levels_from_ref(faders from the reference's stem balance),cmp_run, then drill down:cmp_summary,cmp_arrangement,cmp_sections,cmp_worst,cmp_bars,cmp_zoom(bar).cmp_listtracks progress across runs.
How comparisons score
Every metric sits between two baselines computed from the reference alone: the reference against itself one loop later (its own natural variation, closeness 1) and against itself half a loop out of place (plausible but wrong, closeness 0). Metrics are grouped, and the groups count equally:
- notes: F1 of sounding notes per 16th step, exact pitch and pitch class
- rhythm: F1 and precision of note starts, drum lane hits
- clean: clutter (attacks sharper than the reference), loop self-consistency, loudness share of extra note starts
- sound: band levels, level, transient sharpness, level contour inside the bar
- perceptual: CLAP audio embedding similarity per 2-bar window
The perceptual group exists because the others can all look fine while the result still sounds different, and the clean group exists because note metrics reward clutter. Use cmp_run(stems='demucs') at checkpoints so your render goes through the same separation as the reference. Any change to the scoring should be checked against a known-bad and a known-good draft before you trust it.
Playing live
The same instruments and effects play in real time while the agent edits the music: a jam, a DJ set, a
soundtrack that follows a game or an audience. Hear a recorded set:
three whole songs played live on decks, the set written as one script (live_load, live_deck, live_transition). live_start runs a separate engine process per folder (a local
control port, render workers, a mixer and a safety chain), and the agent drives it with ops:
live_start(bpm) -> live_track(track, instrument, fx) -> live_queue([{track, notes, bars, at: 'next_4'}, ...])
  -> live_status / live_listen(bars) -> more live_queue, live_fx ramps -> live_stop
- Clips loop until replaced, so the music keeps going between the agent's turns. A clip lands on the next
beat, bar or phrase;
after:#kchains a whole arc in one call;live_fxramps sweeps and fades. - Render ahead. Notes render in worker processes seconds before the playhead and the audio callback only copies, so heavy voices (mimic, code voices, guitar performers) play live. A clip whose first notes cannot render in time lands a bar later, and the reply says so.
- It listens to itself.
live_listenruns the same analysis as a render on the last bars played. - Safety. Every output passes a trim, a loudness rider, a lookahead limiter and a ceiling; the limits come
from the environment (
ISMAIL_LIVE_TRIM_DB,ISMAIL_LIVE_CAP_DB,ISMAIL_LIVE_CEILING_DB), never from the agent. - Decks.
live_loadputs a whole ismail song on a cued deck while another plays;live_transitionqueues the mix (blend, bass swap, filter, cut) with a DJ strip per deck (isolator, filter knob, fader, transpose). - Studio and live. The studio code is the source of truth. Effects run live as block-by-block twins held to
the studio versions by tests; an effect with no live twin is baked into each rendered note. A voice with
perform()plays whole phrases live (legato, slides), with bends and vibrato from the clip'sexprlanes.
The skill reference skills/ismail/references/live.md has the method for running a set: read the audience,
steer with small edits, queue a runway before every question, build and drop.
Music videos (optional)
ismail.video makes a music video from a finished song, with every cut and glitch placed from the song's own notes (the event list comes from the project, so the sync is frame exact). It needs pip install -e .[video], Blender 5.x and ffmpeg.
python -m ismail.video init   -s songs/<slug>        # scaffold songs/<slug>/video/
python -m ismail.video sync   -s songs/<slug>        # notes -> frames
python -m ismail.video still  -s songs/<slug> s01_example.py 48
python -m ismail.video render -s songs/<slug> s01_example.py
python -m ismail.video edit   -s songs/<slug> -- --sheet 33 41 16
Shots are Blender scripts built on a small kit (rooms, rigged characters from JSON, lights, fog, cameras), the cut list is Python written in bars, and review is by stills and contact sheets. Per-song work lives in songs/<slug>/video/. The skill reference skills/ismail/references/music-video.md has the full method.
Developing ismail
Songs live in songs/<slug>/, which this repository ignores: a song is never committed here, and a song session
never edits the engine. What a song builds that ismail lacks, it lists in its own HANDOFF.md; engine work happens
on a git worktree branch and comes in through a pull request. The rules (worktrees, never touching another
session's work, never deleting an unmerged branch or worktree, migrating from a song's handoff) are in
skills/ismail/references/development.md.
Tests
python -m pytest tests -q
Round trips: write known material, render it, read it back through the analysis tools. .github/workflows/tests.yml runs them on Ubuntu, macOS and Windows.
Layout
ismail/
  notation.py    note text, step patterns, piano roll
  dsp.py         oscillators, filters, dynamics, delay lines, reverb (numba)
  instruments.py synth, sampler, drums, kit, code
  fx.py          effects; rig.py the guitar rig (fuzz, univibe, amp, cab, rotary, tape, wah)
  render.py      project to audio, dependency ordering, per-track cache, wav/mp3 writers
  analysis.py    audio to text (grid, bars, chords, melody, drums, timbre, formants, compare)
  features.py    16th-step feature grid shared by structure and comparisons
  structure.py   arrangement map, sections, loop detection
  cmp.py         stored comparisons and their views
  perceptual.py  CLAP similarity
  sounddesign.py one-shot rendering, sound distance, parameter fitting
  trackfit.py    in-context fitting against a reference stem
  live/          the live engine: timeline, render workers, mixer graph, decks, safety, live_* ops,
                 block-by-block effect twins (fx_blocks.py, dsp_blocks.py)
  video/         optional music-video pipeline: sync, edit engine, Blender shot kit, CLI
  mimic.py       instruments measured from recordings (partials, body, noise, vibrato, room)
  voices/        the voice library in family folders: keys (grand_piano, additive_piano), strings (violin,
                 cello, contrabass mimic profiles), bass (growl), fx (sfx), guitar (electric), drums (kit70)
  api.py, api_cmp.py, api_sound.py, api_measure.py   the operations (CLI and MCP tools)
  mcp_server.py, guide.py
skills/ismail/   the agent skill (SKILL.md + references)
.mcp.json, .cursor/   MCP and rule config for Claude Code and Cursor
songs/           your projects (git-ignored)
Made something with it?
Open an issue with the song (a link is fine) and the prompt you gave your agent. The best ones go on the showcase page.
License
MIT, see LICENSE.
Ismail Reviews
Login Required
Please log in to share your review and rating for this MCP.
Similar MCP Servers like Ismail
Explore related MCPs that share similar capabilities and solve comparable challenges
MiniMax MCP
Officialby MiniMax-AI
Enables interaction with powerful text‑to‑speech, image generation and video generation APIs through a Model Context Protocol server.
Video Editor MCP
by burningion
Upload, edit, search, and generate videos by leveraging LLM capabilities together with Video Jungle's media library.
ElevenLabs MCP Server
by mamertofabian
Generate speech audio from text via ElevenLabs API and manage voice generation tasks through a Model Context Protocol server with a companion SvelteKit web client.
Flyworks MCP
by Flyworks-AI
Create fast, free lip‑sync videos for digital avatars by providing audio or text, with optional avatar generation from images or videos.
Piapi Mcp Server
by apinetwork
Enables Claude, Cursor, and other MCP‑compatible applications to generate images, videos, audio, text‑to‑speech, and 3‑D models through PiAPI’s extensive media creation models.
Kokoro Text to Speech
by mberg
Generates spoken audio from text, outputting MP3 files locally and optionally uploading them to Amazon S3.
AllVoiceLab MCP Server
by allvoicelab
Generate natural speech, translate and dub videos, clone voices, remove hardcoded subtitles, and extract subtitles using powerful AI APIs.
Youtube Video Summarizer MCP Server
by nabid-pf
Extracts YouTube video captions, subtitles, and metadata to supply structured information for AI assistants to generate concise video summaries.
SunoMCP
by AceDataCloud
Enables AI‑powered music creation, lyric generation, cover/remix production, and audio project management through Ace Data Cloud, exposing a rich set of Model Context Protocol tools for Claude, VS Code, and other compatible clients.